AI Tips for Lawyers: Practical Guide to Research & Drafting
The best AI tips for lawyers involve using specialized tools for legal research, contract analysis, and document review…
The Sanskrit term for Artificial Intelligence is कृत्रिम बुद्धिमत्ता (Kritrima Buddhimattā). ‘Kritrima’ means artificial or man-made, and ‘Buddhimattā’ means intelligence, wisdom, or consciousness. The term directly translates to ‘artificial intelligence’ and reflects the language’s precise, component-based structure, which makes it a subject of interest in computational linguistics.
You’ve probably heard the whisper online, the kind of fascinating fact that sounds too good not to be true: that Sanskrit, an ancient liturgical language, is secretly the perfect language for programming Artificial Intelligence.
The story usually involves NASA, a brilliant ancient grammarian, and the promise of a perfectly logical code that could unlock the future of computing. It’s a compelling narrative. But is it true? Is Silicon Valley about to swap Python for Pāṇini? Or is this just one of the internet’s most persistent and misunderstood urban legends?
Let’s be clear: the hype gets the most important part wrong. But the truth is actually more interesting. The connection between Sanskrit for AI isn’t about writing code; it’s about a 2,500-year-old blueprint for language that computer scientists are still learning from. We’re going to unravel the real story, from the NASA paper that started the rumor to the specific linguistic features that make this ancient language a stunningly modern model for AI.
No, Sanskrit is not the best language for programming AI, and it likely never will be. This is the most common misunderstanding of the entire “Sanskrit for AI” topic. Its value to Artificial Intelligence is not as a practical coding language for writing software—for that, you should absolutely stick with Python.
Instead, Sanskrit’s importance is conceptual. Its highly logical and unambiguous grammatical structure provides a powerful theoretical model for designing better AI systems, especially in the field of Natural Language Processing (NLP). Think of it as an architectural blueprint for building a skyscraper, not the bricks and mortar you actually use to build it.
The Sanskrit term for Artificial Intelligence is कृत्रिम बुद्धिमत्ता (Kritrima Buddhimattā). The phrase is a compound of two words that precisely capture the modern concept.
Like many Sanskrit words, ‘Kritrima Buddhimattā’ is built from logical components, making its etymology clear.
Put them together, and you get a direct and elegant translation: man-made intelligence. This inherent precision is a perfect example of why the language itself is a subject of fascination in computational linguistics.
The idea that Sanskrit has a special relationship with computing isn’t new. It’s a niche academic conversation that has been happening for decades, long before it became an internet meme. The entire story hinges on one key academic paper that was published, misinterpreted, and then amplified into a modern myth.
In 1985, a researcher named Rick Briggs, who was working for NASA’s Ames Research Center, published a paper in AI Magazine titled “Knowledge Representation in Sanskrit and Artificial Intelligence.” This is the document at the heart of the legend.
Briggs argued that modern Natural Language Processing was struggling because natural languages like English are riddled with ambiguity. He proposed that Sanskrit, because of its incredibly rigorous and rule-based grammar, could serve as an ideal, unambiguous intermediate language for representing knowledge in a computer. He pointed to the work of an ancient Indian grammarian named Pāṇini as proof that such a language system was possible.
Crucially, Briggs was not suggesting NASA should start coding rockets in Sanskrit. He was making a theoretical argument for AI researchers to study Sanskrit’s structure as a model for knowledge representation. But the mention of “NASA” and “Sanskrit” in the same breath was all it took. The idea escaped the lab and evolved through a global game of internet telephone into the myth we know today: “NASA says Sanskrit is the best language for computers.”
To understand why Rick Briggs was so impressed, you have to go back to roughly the 5th century BCE and meet the man at the center of it all: Pāṇini. His masterwork, the Ashtadhyayi, is arguably the single most important reason we talk about Sanskrit and AI in the same sentence.
The Ashtadhyayi is a comprehensive grammar of Sanskrit, but calling it a “grammar book” is a massive understatement. It’s more like the source code for the entire language. In about 4,000 highly compact rules, or sutras, Pāṇini laid out a complete, generative system for building correct Sanskrit words and sentences from their base elements (roots and affixes).
Pāṇini’s system is astonishingly similar to modern concepts in computer science. It was, in essence, a formal language theory developed 2,500 years before computers existed.
This is why computational linguists are so fascinated by Paninian grammar. It’s a fully-realized, ancient system that behaves like a modern compiler. It proved that a complex human language could be defined by a finite and logical set of rules.
So, what is it about Sanskrit’s actual structure that makes it so logical? It comes down to a few key features that make it far less ambiguous than a language like English.
In English, word order is king. “The man bites the dog” and “The dog bites the man” mean two completely different things. In Sanskrit, a word’s function in a sentence is determined by its ending—a system called inflection—not its position. The word for “man” would have an ending that marks it as the subject, and the word for “dog” would have one marking it as the object. You could arrange the words in almost any order, and the meaning would remain stable and clear. For an AI trying to perform semantic analysis, this is a massive advantage, as it removes a huge layer of guesswork.
Morphology is the study of how words are formed. Sanskrit has an incredibly sophisticated and regular morphological structure. Complex ideas can be constructed by logically combining root words, prefixes, and suffixes (known as affixes) into a single, often long, compound word.
Think of it like linguistic LEGOs. You have a vast collection of basic root bricks, and you can snap on different pieces to build incredibly specific meanings. This allows for extreme linguistic precision, packing a whole sentence’s worth of English meaning into one well-formed Sanskrit word.
As established by Pāṇini, Sanskrit is governed by a consistent and comprehensive set of rules. While exceptions exist, they are far fewer and more systematized than in English, which is a glorious mess of exceptions, borrowed words, and evolving conventions. For a computer, which thrives on rules and struggles with exceptions, a language built on a logical framework is far easier to parse and understand.
This is where the theory meets potential application. The structural elegance of Sanskrit isn’t just an academic curiosity; it offers tangible models for solving some of the biggest challenges in AI.
NLP is the branch of AI focused on teaching computers to understand and process human language. One of its biggest hurdles is ambiguity. Sanskrit’s structure offers a blueprint for overcoming this.
Knowledge representation is about how to store information in a way that a computer can use to reason and draw inferences. For example, how do you teach a machine that “John is the father of Jane” and “Fathers are male parents” means that “John is a male parent”?
The Paninian system is a masterclass in representing relationships and properties. Its framework for describing linguistic elements and their interactions provides a powerful model for building knowledge graphs—the databases that power modern search engines and AI assistants.
To put Sanskrit’s uniqueness in perspective, let’s see how it stacks up against English (a typical natural language) and a symbolic language like LISP (an early AI programming language).
| Feature | Sanskrit | English | LISP (Symbolic Language) |
|---|---|---|---|
| Grammatical Ambiguity | Very Low | Very High | Zero (by design) |
| Word Order Dependency | Low (meaning from inflection) | High (meaning from position) | Rigid (fixed syntax) |
| Morphological Richness | Extremely High | Low | Not Applicable |
| Rule Consistency | Very High (Paninian system) | Low (many exceptions) | Perfect (it’s code) |
As you can see, Sanskrit occupies a fascinating middle ground. It has the expressive richness of a human natural language but the logical consistency of a formal, man-made one. This unique combination is the real reason it remains a compelling subject in the Sanskrit and Artificial Intelligence conversation.
If Sanskrit is such a perfect model, why aren’t we using it for everything? This is where the hype crashes into reality. The practical hurdles are immense, if not insurmountable.
Modern AI, particularly deep learning, is powered by one thing above all else: massive amounts of data. There are trillions of words of modern English text on the internet for training models. For Sanskrit, the corpus is a tiny fraction of that and consists almost entirely of ancient religious, philosophical, and literary texts. There’s no dataset of everyday Sanskrit conversations, emails, or tweets to train an AI on modern concepts.
Sanskrit is an exceptionally difficult language to master. Its complex grammar, while logical, requires years of dedicated study. You can’t just spin up a team of “Sanskrit AI engineers” the way you can with Python. The pool of experts who deeply understand both Paninian grammar and modern AI is vanishingly small.
Building a software ecosystem is a monumental task. Programming languages like Python are supported by decades of development, with countless libraries, frameworks, compilers, and a global community of developers. For Sanskrit, none of this exists. You would have to build every tool from scratch. It’s simply not a practical endeavor when highly effective tools are already available.
This claim originates from a 1985 paper by NASA researcher Rick Briggs, published in AI Magazine. Briggs argued that Sanskrit’s logical and unambiguous grammar, as documented by the ancient grammarian Pāṇini, made it a suitable model for knowledge representation in AI. The paper was a theoretical exploration of an idea, not a NASA-funded project to make Sanskrit a programming language. Over time, this academic proposal was misinterpreted and amplified by the internet into the popular but inaccurate myth that NASA itself was pursuing Sanskrit for coding.
Pāṇini’s grammar, the Ashtadhyayi, is a set of approximately 4,000 rules that function much like a modern computer program. It uses concepts that are directly analogous to algorithms, functions, and recursion to generate all valid Sanskrit words from their basic roots. Its highly structured, logical, and generative nature mirrors the principles of formal language theory, a cornerstone of theoretical computer science. For this reason, it is often cited as a 2,500-year-old blueprint for computational systems.
While you won’t find Sanskrit in a production AI system at Google, the field of Sanskrit computational linguistics is very much alive in academia. Researchers, particularly at institutions in India (like the IITs) and some Western universities, are actively working on:
This work remains a niche but important field. It’s less about building a commercial product and more about using Sanskrit as a “computational whetstone” to sharpen our understanding of both language and intelligence.
Let’s be decisive. The future of AI will not be coded in Sanskrit. The practical barriers are too high, and the momentum of existing languages is too great.
However, the future of AI and Sanskrit as a source of inspiration is bright. The real value lies in its conceptual legacy. The principles embedded in Paninian grammar—the perfect formalization of a natural language, the power of a rule-based generative system, and the solution to linguistic ambiguity—will continue to influence AI researchers.
The ultimate role of Sanskrit in AI is that of a teacher, not a tool. It’s a 2,500-year-old benchmark for linguistic logic that reminds us of the profound connection between language, structure, and thought. As we build more sophisticated AI, we will likely find ourselves solving problems that Pāṇini already tackled centuries ago, making his work more relevant than ever.
Can I learn Sanskrit to get a job in AI?
Honestly, no. While it’s a fascinating intellectual pursuit, it’s not a practical path to a career in AI. Your time would be far better spent learning Python, understanding data science fundamentals, and mastering modern AI frameworks. The intersection of deep Sanskrit knowledge and professional AI development is an academic niche, not a job category.
Is Sanskrit the only ancient language considered for AI?
Sanskrit gets the most attention by far because of Pāṇini’s uniquely comprehensive and formal grammar, the Ashtadhyayi. While other ancient languages with logical structures exist, none have a surviving ancient text that so completely and algorithmically documents its own grammar. This makes Sanskrit a one-of-a-kind case study for computational linguistics.
What is the main takeaway about Sanskrit and AI?
The key takeaway is that Sanskrit’s value to AI is conceptual, not practical. We will not be writing code in it. Instead, its perfectly logical and unambiguous structure serves as a powerful theoretical model and a source of inspiration for computer scientists working on the hard problems of Natural Language Processing and knowledge representation.

Part of the Thinker's Automation Labs content team. Researches with the SEO Blog Research Agent, drafts the piece, and routes it through review before publishing. Every claim is fact-checked against primary sources.
The best AI tips for lawyers involve using specialized tools for legal research, contract analysis, and document review…
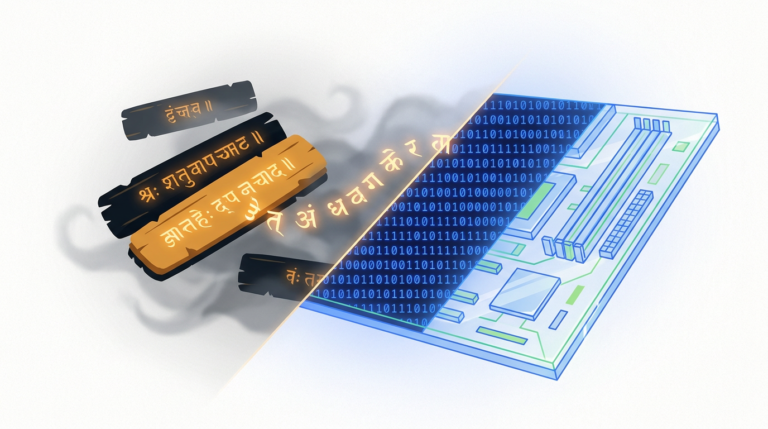
Sanskrit is often cited as ideal for AI due to its highly regular, rule-based grammar codified by Pāṇini.…
AI tips for marketing professionals focus on using artificial intelligence to enhance campaigns and streamline workflows. Key applications…