AI Tips for Lawyers: Practical Guide to Research & Drafting
The best AI tips for lawyers involve using specialized tools for legal research, contract analysis, and document review…
A 1985 paper by researcher Rick Briggs, published in AI Magazine, explored Sanskrit as a potential model for knowledge representation in symbolic artificial intelligence. It did not claim Sanskrit was a programming language or that NASA was adopting it. The paper focused on Sanskrit’s unambiguous grammatical structure.
You’ve seen the post. It pops up every few months on social media, often with a headline that screams, “NASA Says Sanskrit is the Most Computer-Friendly Language!” or something similar. The story suggests that the ancient Indian language is secretly the key to the future of artificial intelligence.
It’s a fantastic story. It’s also almost entirely wrong.
The viral claims are a massive exaggeration of a single, academic paper from 1985. The real story behind the NASA Sanskrit AI paper is far more nuanced, and frankly, more interesting. It’s a tale about a different era of AI, a brilliant linguistic system, and how a good idea from the past doesn’t necessarily fit into the future.
Let’s set the record straight, once and for all.
First, let’s be clear: NASA is not, and has never been, using Sanskrit to program its rockets, rovers, or AI systems. There is no secret project, no hidden directive. The entire myth stems from a fundamental misinterpretation of a research paper that was more of a thought experiment than a practical proposal.
The viral posts you see on social media or in WhatsApp forwards are a classic case of scientific misinterpretation, amplified by a mix of national pride and the internet’s love for a good story. Even a 2018 Forbes article that touched on the subject is often misquoted to support the myth. The reality is much more mundane.
The source of all this confusion is a paper titled “Knowledge Representation in Sanskrit and Artificial Intelligence,” written by a researcher named Rick Briggs. It was published in the spring 1985 issue of AI Magazine, a publication for AI professionals.
Rick Briggs was a researcher at NASA’s Ames Research Center in the 1980s. He was working in the field of artificial intelligence.
AI Magazine, where the paper was published, is a respected journal by the Association for the Advancement of Artificial Intelligence (AAAI). It’s a place for researchers to share ideas, theories, and findings with their peers. Publishing a paper in it is not the same as NASA issuing a formal declaration or adopting a new technology. It’s simply a researcher sharing their work with the scientific community.
Briggs’ paper didn’t claim Sanskrit was a perfect computer programming language. Instead, he argued that Sanskrit, as analyzed by the ancient grammarian Pāṇini, could serve as an ideal model for a system of knowledge representation.
He was fascinated by its structure, which is incredibly precise and rule-based, making it far less ambiguous than modern languages like English. Briggs suggested that the centuries of linguistic analysis that went into codifying Sanskrit grammar could offer valuable lessons for AI researchers who were trying to build systems that could understand and reason about the world.
The paper was about learning from Sanskrit’s structure, not programming in Sanskrit.
The 1985 paper, written by Rick Briggs and published in AI Magazine, proposed that the ancient Indian language Sanskrit could be a useful model for knowledge representation in artificial intelligence. It highlighted the unambiguous, rule-based structure of Paninian grammar as a potential framework for helping computers understand and process information about the world without the ambiguity common in other natural languages. The paper never suggested using Sanskrit as a programming language.
To understand why Briggs was even looking at Sanskrit, you need to understand what AI looked like in 1985. It was a completely different world from the AI of today. The dominant approach was called Symbolic AI.
The core idea of Symbolic AI was to represent the world in a way a computer could understand using symbols and rules. Think of it like trying to teach a computer English by giving it a massive dictionary and a comprehensive grammar book. The goal was to hand-code human knowledge, rule by rule, fact by fact.
This brings us to a critical distinction that gets lost in the myth: the difference between knowledge representation and programming.
Briggs was focused on the second problem. How do you represent complex ideas in a way that a computer can process without getting confused?
This is where Sanskrit entered the picture. Briggs was impressed by the work of Pāṇini, an ancient grammarian who created a comprehensive and highly logical system of about 4,000 rules that perfectly describe Sanskrit grammar.
This Paninian grammar creates a language with very little ambiguity. In English, a sentence like “I saw the man on the hill with a telescope” can mean several things. Did you use the telescope? Did the man have it? Was the man on a hill that also had a telescope? Sanskrit’s grammatical structure largely eliminates these kinds of problems.
Briggs saw this as a ready-made solution for knowledge representation. Why reinvent the wheel when ancient linguists had already created a perfectly logical system for encoding meaning?
While Briggs’ paper was an interesting piece of computational linguistics for its time, the ideas in it are almost completely irrelevant to how AI is actually built today. The entire field took a sharp turn away from the path he was exploring.
The Symbolic AI approach of the 1980s largely failed. Why? Because the real world is messy, and trying to write a rule for everything is impossibly complex and brittle.
Instead, the field shifted to a statistical approach, which we now call machine learning and deep learning. This approach doesn’t try to teach the computer rules. Instead, it feeds the computer massive amounts of data and lets it figure out the patterns on its own.
Think of it this way:
Modern AI won this showdown, and it’s not even close. The precision of Sanskrit’s grammar is a solution to a problem that modern AI simply sidesteps.
If you walk into any AI lab today—at Google, Meta, OpenAI, or even NASA—you won’t find anyone writing code in Sanskrit. You’ll find them using Python.
The real languages of AI are programming languages like Python, combined with specialized libraries like TensorFlow and PyTorch. These tools are designed for the heavy-duty mathematics and data manipulation required for machine learning, not for representing knowledge with grammatical rules. The entire paradigm is different.
AI researchers in the 1980s, like Rick Briggs, studied Sanskrit because they were working within the paradigm of Symbolic AI. This approach required a formal, unambiguous way to represent human knowledge for computers. Sanskrit, with its highly structured Paninian grammar, offered a pre-existing, logically consistent system for encoding meaning without the ambiguity found in other natural languages, making it a compelling subject for research in knowledge representation.
So if the paper is from 1985 and the technology is obsolete, why does this story keep coming back? The answer has more to do with sociology than technology.
For many, the idea that an ancient language from India holds the key to a futuristic technology is a source of immense cultural and national pride. It feels like a validation of ancient wisdom on the world’s modern stage. This powerful narrative is perfectly engineered for social media, where compelling stories travel faster than complicated facts.
The myth persists because it tells a better story than the truth. The truth is that a researcher had a clever but ultimately niche idea that the field of AI moved on from. The myth is that ancient genius is about to power the future. It’s not hard to see which one gets more shares.
The gap between Briggs’ vision and today’s AI is enormous. It’s a difference in the fundamental philosophy of how a machine can “know” something.
Briggs envisioned a rule-based system where knowledge was explicit. The computer would have a fact database: Socrates -> is_a -> human, human -> is_a -> mortal. To conclude Socrates is mortal, it would follow this logical chain.
Modern AI, especially Large Language Models (LLMs) like ChatGPT, doesn’t work like that. It uses a concept called embeddings. In simple terms, an embedding turns a word or a concept into a long list of numbers (a vector). This vector represents the word’s “location” in a vast, multi-dimensional space of meaning.
Words with similar meanings, like “king” and “queen,” end up close together in this space. The relationship between words can even be captured with math. For example, the vector for “king” minus “man” plus “woman” results in a vector very close to “queen.”
When you ask ChatGPT a question, it’s not looking up facts in a database. It’s using its massive transformer architecture to calculate the most probable sequence of words to generate next, based on the patterns it learned from training on nearly the entire internet.
Knowledge isn’t stored as explicit rules; it’s an emergent property of the statistical relationships between trillions of words and phrases. This is a messy, probabilistic, and incredibly powerful way of handling language—and it’s the polar opposite of the clean, logical, rule-based system Briggs admired in Sanskrit.
In modern AI like ChatGPT, knowledge is not represented by explicit rules or facts. Instead, it is encoded implicitly through “embeddings” within a neural network. Words, phrases, and concepts are converted into numerical vectors in a high-dimensional space. The position and relationship of these vectors, learned from analyzing massive datasets, capture the meaning and context. The AI generates responses based on the statistical probabilities of these relationships, rather than logical deduction.
It’s easy to look back and dismiss Briggs’ paper, but that would be a mistake. It was a thoughtful piece of linguistic analysis that asked a very important question: how can we deal with the inherent ambiguity of natural language processing?
He was right to identify ambiguity as a central challenge for AI. His proposed solution, borrowing from Sanskrit, was clever. It just so happens that the entire field found a completely different, more scalable way to solve the problem.
The paper is a fascinating snapshot of a particular moment in AI history. It’s a reminder that the path of technology is not a straight line. Many good ideas are explored, and most are left behind for something that works better. The Sanskrit for artificial intelligence 1985 paper is one of those clever ideas. Interesting, but ultimately, a dead end.
No, Sanskrit is not a good language for computer programming. Programming languages are formal, artificial languages designed specifically to give unambiguous, step-by-step instructions to a computer. Sanskrit is a natural human language, and while it is highly structured, it is not designed for this purpose. The myth confuses its potential for knowledge representation in an old AI paradigm with its suitability for programming, which are two very different things.
So, did NASA have anything to do with this at all?
Rick Briggs was a NASA employee when he wrote the paper, and he was working at a NASA research center. That’s the only connection. NASA, as an organization, never adopted or promoted his findings.
Could Sanskrit be used for AI in the future?
It’s highly unlikely in the way modern AI is developing. The current paradigm is based on statistical machine learning with massive datasets, a field where the structural properties of Sanskrit offer no practical advantage over the tools already in use, like Python.
Why do people keep sharing this misinformation?
It’s a combination of factors: it’s a compelling story, it taps into cultural and national pride, and the technical details are complex enough that a simple, exciting (but wrong) summary is easier to share and believe than a nuanced explanation.
Is there any value in studying Sanskrit today?
Absolutely. It is a language of immense historical, cultural, and literary importance. Its sophisticated grammatical structure is a monumental intellectual achievement. Its value lies in linguistics, history, and literature, not in modern computer science.

Part of the Thinker's Automation Labs content team. Researches with the SEO Blog Research Agent, drafts the piece, and routes it through review before publishing. Every claim is fact-checked against primary sources.
The best AI tips for lawyers involve using specialized tools for legal research, contract analysis, and document review…
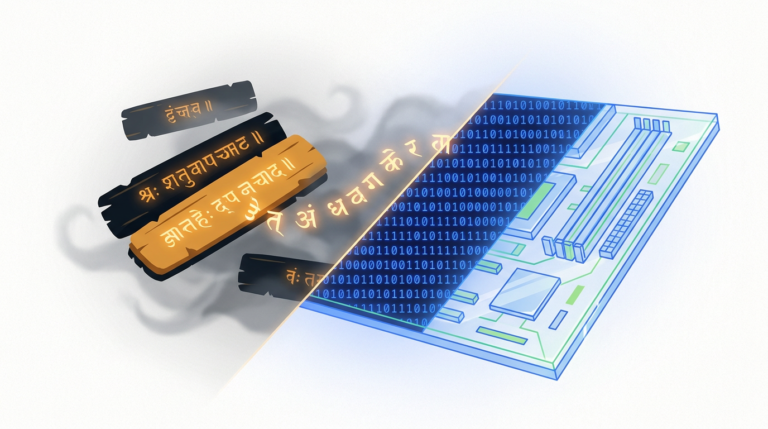
Sanskrit is often cited as ideal for AI due to its highly regular, rule-based grammar codified by Pāṇini.…
AI tips for marketing professionals focus on using artificial intelligence to enhance campaigns and streamline workflows. Key applications…