Generative AI for Business: A Real-World How-To Guide
Generative AI for business refers to artificial intelligence systems that create new, original content—like text, images, and code—from…
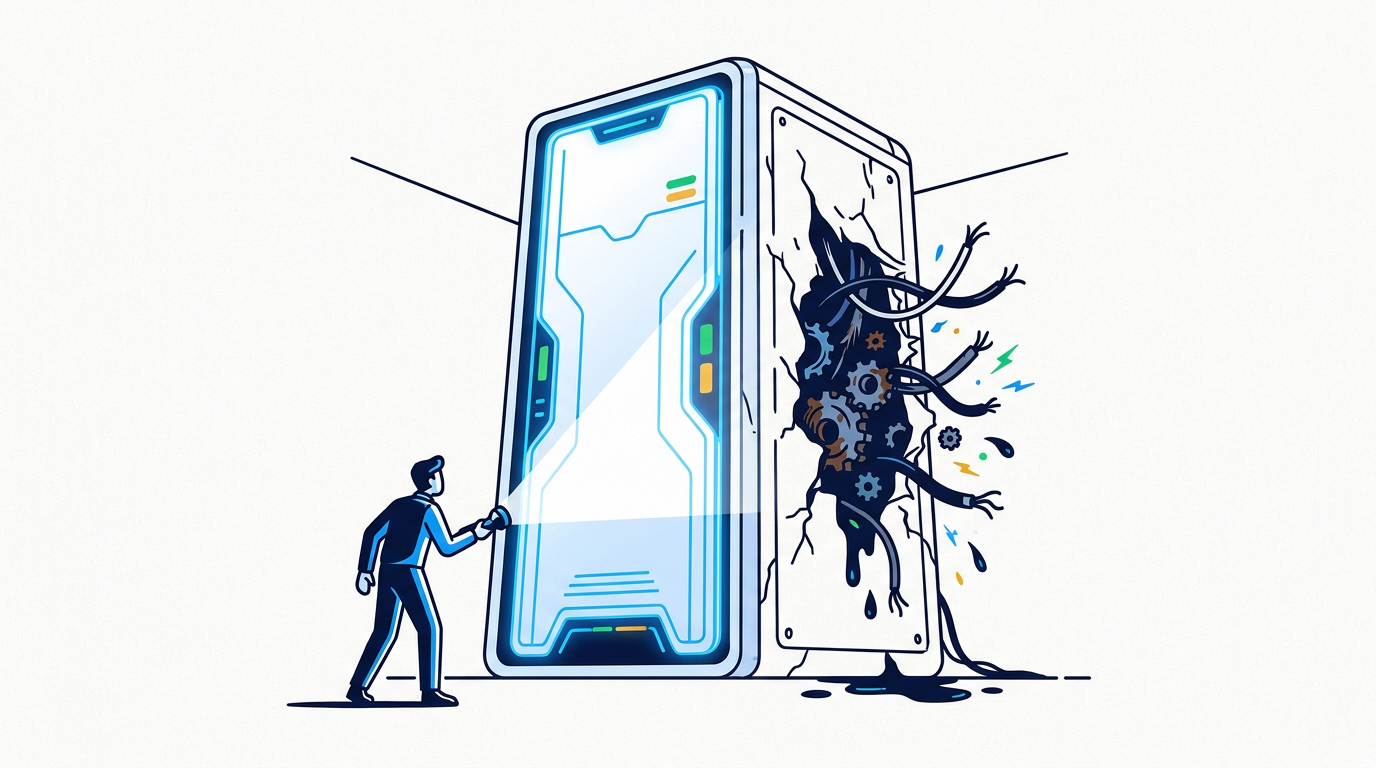
Generative AI’s primary limitations include producing factually incorrect information (hallucinations), inheriting biases from its training data, and posing significant data privacy risks. It also lacks common sense, raises complex copyright issues, and requires immense computational resources, creating ethical and environmental concerns.
Let’s get one thing straight: generative AI is an incredible tool. But it’s also a deeply flawed one. The hype train would have you believe we’re on the verge of artificial general intelligence, but the reality on the ground is much messier, more awkward, and frankly, more interesting. The current state of AI is less like a flawless super-brain and more like a brilliant, erratic intern who sometimes makes things up with unnerving confidence.
Ignoring the very real limitations of generative AI isn’t just naive; it’s a recipe for disaster. If you’re a business owner, creator, or marketer trying to use these tools, you need to know where the landmines are. This isn’t a doom-and-gloom post. It’s a practical guide to the problems with AI, so you can use it wisely without getting burned. We’ll cover the awkward truth about what generative AI still gets wrong, from factual errors to the hidden environmental costs nobody talks about.
If you’ve used any large language model (LLM) like ChatGPT for more than five minutes, you’ve probably seen it happen. You ask for a fact, a source, or a summary, and it returns an answer that sounds plausible, authoritative, and is completely, utterly wrong. This is the single biggest and most frustrating limitation of generative AI today.
AI hallucinations are when a model generates false, nonsensical, or factually incorrect information but presents it as if it were true. It’s not lying in the human sense—it has no intent to deceive. It’s just… hallucinating.
Think of it this way: an LLM is a super-advanced prediction engine. Its entire job is to predict the next most probable word in a sequence, based on the patterns it learned from its massive training data. It’s not consulting a fact-checked encyclopedia; it’s running on statistical probability. A hallucination happens when the most statistically likely response doesn’t align with reality. The AI isn’t “thinking”; it’s just stringing together words that feel right based on its programming, which can lead to fabricated information.
This is the most immediate risk for anyone using AI for serious work. An AI might invent a legal precedent that doesn’t exist, cite a scientific study that was never published, or create a quote from a historical figure who never said it.
These factual errors are dangerous because they sound so convincing. The tone is always confident. The language is always fluent. Without a human expert to double-check the output, misinformation can easily slip into reports, articles, and marketing copy. For a business, this is a direct path to lost credibility and potential legal trouble. Never, ever trust an AI’s factual claims without independent verification.
Generative AI models are trained on vast swathes of the internet—a dataset that includes books, articles, forums, and websites. In other words, they are trained on us. And unfortunately, that means they learn all of our biases, stereotypes, and prejudices.
If historical training data predominantly shows doctors as men and nurses as women, the AI will reinforce that stereotype. If a model is trained on text that contains racial or gender bias, its outputs will reflect that bias. This isn’t a theoretical problem. We’ve seen AI hiring tools that penalize female candidates and image generators that produce stereotypical depictions of different ethnicities.
The core issue is that the training data is a mirror of our often-flawed society. Cleaning this data of all human bias is a monumental, perhaps impossible, task. This means a constant risk of AI tools producing biased, unfair, or offensive content, which can cause serious reputational damage.
When you type a query into a public generative AI tool, where does that data go? The short answer: you should assume it’s not private.
Most consumer-facing AI tools use your conversations to further train their models. This is a huge data privacy risk. If your employees are pasting sensitive company information, client details, or confidential code into a public chatbot, that data could be absorbed into the model. It could then, potentially, be surfaced in a response to another user’s query down the line.
This is one of the most significant risks of generative AI for business. Using these tools without a clear policy and, ideally, a private, enterprise-grade version is like leaving your company’s filing cabinet open on a public sidewalk. Your confidential information is only as secure as the AI provider’s terms of service, which you probably haven’t read.
The world of AI and intellectual property is a legal minefield right now, and nobody has a good map. The central conflict is twofold:
This uncertainty creates huge risks. If you use AI-generated images or text in your business, are you unknowingly committing copyright infringement? The courts are still battling this out, and the lack of clarity is a major disadvantage of generative AI for commercial use.
Here’s a problem with AI that rarely makes headlines: the enormous environmental toll. Training and running large-scale generative AI models is an incredibly resource-intensive process.
These models run in massive data centers packed with thousands of specialized computer chips. Training a single large model, like GPT-4, consumes a staggering amount of electricity—enough to power thousands of homes for a year. On top of that, these data centers require immense volumes of fresh water for cooling. A single query to an advanced AI can use a surprising amount of energy.
As AI becomes more integrated into our daily lives, its carbon and water footprint will only grow. This is a serious ethical issue that the industry is just beginning to confront.
As we rely more on AI, new security vulnerabilities emerge. Two of the biggest are prompt injection and data poisoning.
These are not just theoretical risks; they are active security challenges that AI developers are grappling with right now.
Building a frontier large language model isn’t something you can do in your garage. It’s an industrial-scale operation with a price tag in the billions. The cost comes from a few key areas:
This massive cost creates a significant barrier to entry, concentrating power in the hands of a few tech giants. It stifles competition and means that the future of this powerful technology is being decided by a very small group of corporations.
One of the most unsettling limitations of generative AI is its lack of explainability. For many complex models, even the engineers who built them don’t know exactly why the AI produced a specific answer. This is known as the “black box” problem.
We can see the input (the prompt) and the output (the response), but the reasoning process in the middle is a complex web of mathematical calculations that is not interpretable to humans. This is a massive problem in high-stakes fields. If an AI recommends a medical diagnosis or a financial trade, you need to know its reasoning. Without explainability, you can’t trust the output for any critical decision.
When an AI gets something wrong and causes real-world harm, who is legally responsible?
Imagine an AI-powered legal tool gives a user bad advice, causing them to lose a case. Or a self-driving car guided by AI causes an accident. Who is at fault? The user who relied on the AI? The company that developed the AI? The company that provided the training data?
Our legal system was not built for a world where non-human agents make autonomous decisions. This legal gray area is a huge hurdle for the adoption of AI in critical sectors like healthcare, finance, and transportation, as the question of liability remains dangerously unresolved.
If you can use an AI to write your emails, draft your reports, and brainstorm ideas, what happens to your own ability to do those things? This is the risk of “skill fade” or skill atrophy.
Just like relying on a calculator can weaken your mental math skills, over-reliance on AI could dull our own critical thinking, writing, and problem-solving abilities. The key is to use AI as a partner or a tool for augmentation, not as a crutch or a replacement for thought. The “AI will replace writers” debate is the wrong conversation. The real risk is that we stop trying to be good writers ourselves. This is a subtle but profound long-term risk of generative AI.
As AI-generated content has flooded the internet, a cottage industry of AI detectors has emerged, promising to tell you whether a piece of text was written by a human or a machine.
Our opinion? Skip them. They don’t work reliably.
These tools are notoriously inaccurate. They frequently produce false positives (flagging human writing as AI) and false negatives (missing AI-generated text). They are especially bad at judging text from non-native English speakers. Furthermore, as AI models get better, they become harder to detect, and it’s simple to use another AI tool to “humanize” text to evade detection. Relying on these detectors for anything important, like academic integrity or hiring decisions, is irresponsible.
After all these warnings, you might be tempted to unplug the AI and go back to a pen and paper. But that’s not the answer. Generative AI is a powerful tool, and ignoring it is a mistake. The key is to use it with your eyes wide open.
Here’s our framework for using AI safely and effectively:
By understanding the disadvantages of generative AI, you can avoid the most common pitfalls and harness its strengths without falling for the hype.
The main disadvantages of generative AI are its tendency to produce factually incorrect information (hallucinations), its potential to reproduce and amplify biases from its training data, and significant data privacy and security risks. It also faces challenges with copyright, high operational costs, and ethical issues like its environmental impact.
An AI hallucination is when a generative AI model produces a response that is false, nonsensical, or not based in reality, but presents it as fact. It happens because these models are designed to predict the next most statistically likely word in a sequence, not to verify facts. They are essentially creative writing engines, not databases, so they can confidently invent information that fits a linguistic pattern.
Bias gets into generative AI models primarily through their training data. These models learn from vast amounts of text and images from the internet, which reflect existing societal biases related to gender, race, and culture. If the data contains stereotypes or underrepresents certain groups, the model will learn and replicate those biases in its own outputs.
For businesses, the biggest risks include: generating and publishing misinformation that damages credibility; data leaks from employees inputting confidential information into public AI tools; copyright infringement issues from using AI-generated content; and reputational damage from producing biased or unethical outputs. There is also a risk of legal liability for any harm caused by AI-generated advice or content.

Part of the Thinker's Automation Labs content team. Researches with the SEO Blog Research Agent, drafts the piece, and routes it through review before publishing. Every claim is fact-checked against primary sources.
Generative AI for business refers to artificial intelligence systems that create new, original content—like text, images, and code—from…
Generative AI examples include tools that create original content across various formats. Common applications are text generation with…
Generative AI creates Multiple Choice Questions (MCQs) by analyzing source material with a large language model to produce…